Recent work in econometrics, online learning, and machine learning.
Robust Bayes Treatment Choice with Partial Identification
Accepted
With José Luis Montiel Olea, Jörg Stoye, Chen Qiu, and Serdil Tinda
•Econometric Theory
We study a class of binary treatment choice problems with partial identification through the lens of robust (multiple prior) Bayesian analysis. We use a convenient set of prior distributions to derive ex-ante and ex-post robust Bayes decision rules, both for decision makers who can randomize and for decision makers who cannot.
Our main messages are as follows: First, ex-ante and ex-post robust Bayes decision rules do not agree in general, whether or not randomized rules are allowed. Second, randomized treatment assignment for some data realizations can be optimal in both ex-ante and, perhaps more surprisingly, ex-post problems. Therefore, it is usually with loss of generality to exclude randomized rules from consideration, even when regret is evaluated ex post.
We apply our results to a stylized problem where a policy maker uses experimental data to choose whether to implement a new policy in a population of interest, but is concerned about the external validity of the experiment at hand (Stoye, 2012); and to the aggregation of data generated by multiple randomized control trials in different sites to make a policy choice in a population for which no experimental data are available (Manski, 2020; Ishihara and Kitagawa, 2021).
Epsilon-Minimax Solutions of Statistical Decision Problems via the Hedge Algorithm
Revise & Resubmit Requested
With José Blanchet, José Luis Montiel Olea, Jörg Stoye, Chen Qiu, and Lezhi Tan
•Journal of Econometrics, Extended Abstract Publisedh in EC '25
A decision rule is $\epsilon$-minimax if it is minimax up to an additive factor epsilon. We present an algorithm for provably obtaining epsilon-minimax solutions for a class of statistical decision problems. In particular, we are interested in problems where the statistician chooses randomly among I decision rules. The minimax solution of these problems admits a convex programming representation over the $(I-1)$-simplex. Our suggested algorithm is a well-known mirror subgradient descent routine, designed to approximately solve the convex optimization problem that defines the minimax decision rule. This iterative routine is known in the computer science literature as the hedge algorithm and is used in algorithmic game theory as a practical tool to find approximate solutions of two-person zero-sum games. We apply the suggested algorithm to different minimax problems in the econometrics literature. An empirical application to the problem of optimally selecting sites to maximize the external validity of an experimental policy evaluation illustrates the usefulness of the suggested procedure.
Approximate Least-Favorable Distributions and Nearly Optimal Tests via Stochastic Mirror Descent
Working Paper
With Lezhi Tan, José Luis Montiel Olea, Chen Qiu, and José Blanchet
We consider a class of hypothesis testing problems where the null hypothesis postulates $M$ distributions for the observed data, and there is only one possible distribution under the alternative. We show that one can use a stochastic mirror descent routine for convex optimization to provably obtain - after finitely many iterations - both an approximate least-favorable distribution and a nearly optimal test, in a sense we make precise. Our theoretical results yield concrete recommendations about the algorithm's implementation, including its initial condition, its step size, and the number of iterations. Importantly, our suggested algorithm can be viewed as a slight variation of the algorithm suggested by Elliott, Müller, and Watson (2015), whose theoretical performance guarantees are unknown.
With Victor Chernozhukov, Carlos Cinelli, Sven Klaassen, Whitney Newey, Martin Spindler, Jan Teichert-Kluge, and Suhas Vijaykumar
Text, images, and other rich covariates are increasingly compressed into AI-learned representations and then used as controls in causal analysis. We study when this approach is valid and develop a practical framework for causal inference with learned representations. For a broad class of estimands, an imperfect representation distorts the target causal parameter by the product of two representation errors: one in the outcome regression and one in the balancing weight (or Riesz representer). This yields three constructive results. First, cross-fitted double machine learning (DML) provides valid Wald inference for the representation-dependent target. When representation errors are small, the same interval covers the causal parameter, and it can even attain the semiparametric efficiency bound. Second, fold-wise representation learning (or fine-tuning) is compatible with DML inference for the causal parameter. To this end, we develop convex- and star-aggregation pipelines for learning and combining representations. Third, when representation errors are substantial, we can provide interpretable sensitivity regions and root-$n$ inference for their endpoints. In a multi-modal demand application, seven representation-specific estimates and their star aggregate all imply a negative near-unit elasticity for rank-based price response, and the result remains robust over the reported sensitivity grid.
Drafts in preparation. Available upon request unless linked.
Econometrics of Salience
Draft coming soon!
With Levon Barseghyan and Francesca Molinari
Mirror Descent Framework for Edge of Stability
In Progress
Working draft
We train a fully-connected multilayer perceptron with two hidden layers on the CIFAR-10 dataset. To train this model, we implement full-batch gradient descent (GD), stochastic gradient descent (SGD), Adam, and various other mirror descent optimizers, varying the learning rate to investigate the sensitivity of Edge of Stability (EoS) phenomena. We find limited evidence that mirror descent routines, when trained on the same dataset and optimizing the same neural architecture, trains at the EoS, while we are able to reproduce full-batch GD results from Cohen et al. (2021). Our results suggest non-GD mirror descent routines may not train at EoS as often as full-batch GD.
Transfer Performance Evaluation Using Bayes Methods
In Progress
Working draft
I study Bayesian approaches to constructing uncertainty quantification for out-of-sample prediction performance,
and compare them to alternative frequentist methods in the recent literature.
From May to July 2023, I was a Research Assistant at Columbia Business School working under Professor Jing Dong. The premise of the project was the increased prevalence of AI diagnostic technologies (such as IDx-DR) has called into question how current diagnostic workflows can be altered in order to improve patient outcomes. This project took the approach of utilizing stochastic modelling and results in queueing theory to provide a proposed solution to the issue. At the end of the program, I summarized my results in a presentation given to a crowd of fellow RAs, PhD students, and faculty. The presentation, written in LaTeX Beamer, is attached below.
Labor Dynamics Institute Work
From January 2022 to January 2023, I was an Undergraduate Researcher at the Labor Dynamics Institute at Cornell University under Professor Lars Vilhuber. In this work, I replicated numerous economics research papers submitted to a variety of American Economics Association Journals (e.g., AEJ, AER, AEP, etc.), making use of version-control softwares such as GitHub, Bitbucket, and Code Ocean. I also made heavy use of Stata, R, Python, and Matlab. Aside from replication of papers, I also contributed to the replication template used by all of the research assistants in the Replication Lab. The GitHub to said template is linked below.
Other Work
Normal Numbers Notes
I recently compiled a very brief set of notes about normal numbers mainly based on other sources I came across as I learned about normal numbers.
Logistic Map
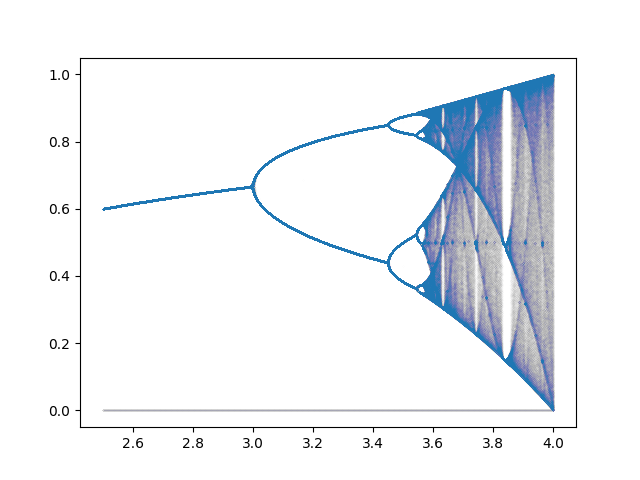
I have coded a Python program to graph the Logistic Map and its chaos and windows. It works by going a certain number of iterations out for initial conditions iterated through an equally spaced set of points between 0 and 1 as the parameter r changes.
Nonstandard Analysis
On December 8th, 2022, I gave a brief lecture on Nonstandard Analysis to undergraduates, graduates, and mathematics faculty. In this lecture, I constructed the hyperreals, discussed the powerful Existential Principle, and briefly motivated possible applications of nonstandard analysis to large economies.
Axiom of Choice Research
Together with James (Ruogu) Zhang, I researched and later gave a lecture to a group of math undergraduates as well as math faculty on the Axiom of Choice. This lecture not only motivated the existence of the Axiom of Choice, but also consisted of elaborate proofs demonstrating the equivalence of the Axiom of Choice to other assumptions, such as Zorn's Lemma, the Well-Ordering Principle, every vector space having a basis, and also a discussion of non-measurable sets, with the Vitali Set being used as a chief example. We also utilized transfinite recursion in some of our equivalence proofs.
Derivation of the Hyperbolic Angle Formula
I have written a short paper that derives the formula for the hyperbolic angle in terms of the coordinates of the unit hyperbola.